MEASURED,
WRITTEN DOWN.
We write up the measurements as they happen, and we leave the losing rows in the tables. Every post is dated and names the runs it came from, because a number you cannot trace back to a run is marketing.
-
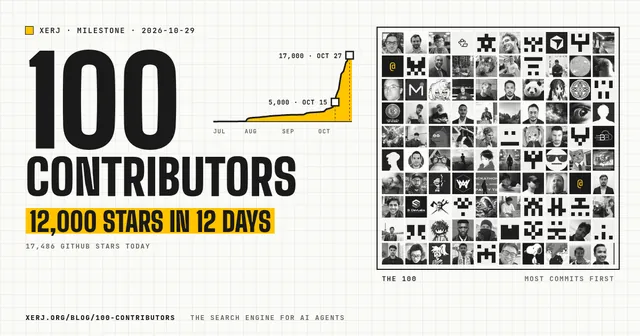
· MILESTONE · 100 CONTRIBUTORS
100 contributors behind 12,000 stars in 12 days
Meet the 100 contributors behind XERJ. In 12 days it gained 12,434 GitHub stars and became the #1 Rust repository of the day and week on Trendshift. What they built, what your agents get now, and where it goes next.
AUTHOR · XERJ ENGINEERING · PUBLISHED · 2026-10-29
READ THE POST → -
· PERFORMANCE · AUTOINDEX + SEARCH
How your field reports made XERJ autoindex faster
Index size per indexed byte fell from 3.50x to 1.80x of source, and autoindex makes at most 32 datasets where one folder used to need 454 indices. Six improvements explained in plain terms, the performance gate behind them, and a thank-you to the 28 people and 217 agent field reports that made it happen.
AUTHOR · XERJ ENGINEERING · PUBLISHED · 2026-10-26
READ THE POST → -
· RELEASE · V1.0.0-RC.99
rc.99: smart, resource-aware autoindex and more harness tools
rc.99 is yours: 116 merged changes and the 20 community members behind them. A laptop stays usable while it indexes, and an agent can ask up to 50 questions in one call and get cited evidence back. Memory exhaustion and clustering stay open. This is the 98th tagged release, just over 100 days since rc.1.
AUTHOR · XERJ ENGINEERING · PUBLISHED · 2026-10-24
READ THE POST → -
· CORPUS HUB · XERJ ASK
Corpus Hub v2: ask the question, get the one pack that answers it
Type a question and
xerjpicks the corpus from a signed catalogue, pulls that one pre-indexed pack (lz4: 4.4 MB) and answers on your machine: 1.7 to 2.3 s cold, 37 to 57 ms warm. Ambiguous questions come back as a choice (exit 4), and a dead hub now has its own code (exit 6). The hub site gained contributor pages, agent scores kept apart from human stars, per-corpus traffic and field reports that become PRs. The routing miss we hit, and the catalogue lagging the packs (14 routable of 251 built), are in the post.AUTHOR · XERJ ENGINEERING TEAM · PUBLISHED · 2026-10-19
READ THE POST → -
· CYBER-EXPLOITS CORPUS · EVAL
The exploit hub, tested on three fresh CVEs
One query over 1.09 million PoC documents named the exact route and field for CVE-2026-23744; an in-corpus 2026 exploit named the exact denylist segments the vendor shipped for CVE-2026-105844; the third case proved the corpus adds nothing when its stratum is empty, and we count it. The vendor patch beat both arms on the needle, the eval caught a live client defect, and the losses are in the tables.
AUTHOR · XERJ ENGINEERING · PUBLISHED · 2026-10-08
READ THE POST → -
· GUEST · AGENT MEMORY · EVAL
Six eval scars from a production agent-memory system
We asked practitioners what agents still miss. Chunxiao Wang (Assay / nautilus-compass) answered with six patterns that each cost a real failure: topic slicing that beat token windows on recall@1 by double digits and reversed two embedders' MTEB ranking; a 0.87 classifier a 0.78 always-yes baseline nearly matched at n=60; the masking bug that scores every query zero; and the paired-vs-unpaired read that overstated an effect 4×. Their price was an honest answer to where our corpus registry is thin against their workload. We checked: zero of 99 live corpora are agent trajectories, and our chunking is the wrong shape for topic-sliced session memory. The want now has a named backlog slot.
GUEST · CHUNXIAO WANG, ASSAY / NAUTILUS-COMPASS · PUBLISHED · 2026-10-07
READ THE POST → -
· CORPUS HUB · AGENT CONTEXT
The Corpus Hub: pinned, licenced, signed, and contributed by pull request
Agent context is everyone's private plumbing: unknown vintage, unknown licence, no checksum, no signature. The Corpus Hub makes it a registry — four reference corpora and a signed daily pack, every source pinned to the SHA the build used and licence-reviewed by a human. The measured use case: same 16/16 solve rate at 2.7× fewer output tokens. And the experiment we did not want: our own security A/B tied — zero findings traceable to the corpus — so the hub ships with that row in the table and a code-shaped pack as its roadmap.
AUTHOR · XERJ ENGINEERING TEAM · PUBLISHED · 2026-10-01
READ THE POST → -
· RELEASE GATES · ENGINEERING
The rc.80 gates: three passed outright, three failed, one split
The ten-item program shipped, and every gate that could carry a number was run in public. /_ask scored macro-F1 0.9975 at p50 1.129 ms; xerj_map took unknown-field 400s from 20/30 to 0/30; calibration took FiQA ECE from 0.3109 to 0.0088. The local judge lost everywhere it was measured, the flywheel covered 19.72% against an 80% bar, and the decide head missed its accuracy bars — those rows are in the post too, and they filed four issues.
AUTHOR · XERJ ENGINEERING TEAM · PUBLISHED · 2026-09-30
READ THE POST → -
· CORPUS PACKS · SECURITY DATA
One vulnerability, three names, and a pack we sign
The same Rust vulnerability sits in two databases under three ids, and neither database merges them. A three-line identity recipe collapses 4,107 filings to 1,950 records carrying every field either source knew — including the curated vulnerable-function paths no export has. Then the part nobody ships: a signature, because checksums prove integrity and not origin.
AUTHOR · XERJ ENGINEERING TEAM · PUBLISHED · 2026-09-27
READ THE POST → -
· STORAGE · ENGINEERING
Cutting the index 28%: dissect first, write Rust second
Four file formats, each changed only after a real segment was dissected offline. The stored section fell −73.1%, term metadata −93.1%, and the whole index went from 5.52 MB to 3.99 MB. The variant we were most confident about doubled the size it was improving — that row is in the post too.
AUTHOR · XERJ ENGINEERING TEAM · PUBLISHED · 2026-09-27
READ THE POST → -
· BENCHMARKS · DECISIONS
A BM25 vote ties Jev on spam and beats it on intent
Five hundred decisions each, on two public datasets. On spam the two are statistically indistinguishable (McNemar p = 0.75). On 77-way intent a local vote wins by nine points at zero marginal cost. The crossover is twenty-five labelled examples per class. On DBpedia Jev beats us outright, and that row stays in.
AUTHOR · XERJ ENGINEERING TEAM · PUBLISHED · 2026-09-22 · UPDATED · 2026-09-27
READ THE POST → -
· BENCHMARKS · JEV
Does XERJ beat JEV? On the bill, outright. On FiQA, no.
Does XERJ beat JEV? On the bill, outright — the FiQA rerank run billed $0.6375 and 15,178,758 judge tokens, while our local node answers the same wire with zero. On relevance the hosted judge keeps SciFact (0.7410 vs 0.6993) and FiQA (0.3638 vs 0.2382, +0.126); our zero-API-token hybrid keeps NFCorpus (0.3448 vs 0.3312). And the unmodified pip jev-reranker passed its own gate against a XERJ node. Every win, every loss, with the receipt.
AUTHOR · XERJ ENGINEERING TEAM · PUBLISHED · 2026-09-21 · UPDATED · 2026-09-27
READ THE POST →
More measured ground lives in the benchmarks hub: /benchmarks — the ES conformance board, BEIR baselines, and the Jev tables, every number traced to a run.
If you would rather check a number than read about it: the engine is one binary, the quickstart walks a first index, the playground needs no install, and your own corpus is the benchmark that matters — the standard every post above holds itself to.